AI ENGINEER
AGENT SYSTEMS & DOCUMENT AI
I take LLM agents and agentic workflows from prototype to production, and build the document processing, OCR and retrieval pipelines they depend on.
My Work
I take LLM agents and agentic workflows from prototype to production, and build the document processing, OCR and retrieval pipelines they depend on.
My WorkI build AI systems that hold up in production: agents that reason and act, retrieval they can trust, and evaluation that proves it.
Multi-step LLM agents with tool use, memory and reasoning. I also build query-to-agent routing and stateful workflows that coordinate several specialist agents.
Containerised microservices on self-hosted and cloud GPU infrastructure (Docker, FastAPI, Celery/Redis, vLLM). Every service runs with CI/CD and is monitored for quality, latency and cost.
End-to-end pipelines that turn unstructured, scanned documents into structured, validated data using OCR, layout analysis, embeddings and LLM-based extraction. They cut processing time from days to hours.
Hybrid retrieval (BM25 + dense), cross-encoder reranking and knowledge graphs. Eval-driven optimisation raised extraction accuracy by +20% F1.
Reproducible evaluation harnesses with Langfuse and DeepEval, plus A/B benchmarking. Guardrails cover prompt-injection mitigation, output validation and GDPR-aware data handling.
PEFT / QLoRA with TRL for domain-specific document intelligence. Each tuned model is benchmarked against proprietary APIs on accuracy, latency and cost.
Selected open-source work on agents, retrieval, evaluation and LLM serving. Each project links to its code on GitHub, and some have walkthroughs on YouTube or write-ups on Medium.
An end-to-end data platform on the German Bundestag open-data API. Raw data lands in Bronze, is cleaned into Silver and modelled into a Gold star schema, all incremental, tested and orchestrated with Airflow.
Compares a knowledge-graph GraphRAG pipeline with traditional vector RAG on multi-hop QA. Comes with tracing, LLM-as-judge metrics and orchestration.
Measures prompt/KV caching with real cold-vs-warm experiments. In one test, a warm cache cut time to first token by 26x.
Benchmarks open-source guardrails on toxicity, PII leaks, jailbreaks and format adherence, and measures how much latency each one adds.
 spaCy, NetworkX, Sentence-Transformers
Qdrant, Ollama, Streamlit
A fully local GraphRAG system: knowledge-graph construction and retrieval where no data leaves the host.
 Tesseract OCR, LLM (Gemini)
Streamlit, Prefect, Selenium
An OCR + LLM pipeline that parses resumes and matches them against scraped job postings.
 Gradio, FastAPI, Whisper
LlamaIndex, PyMuPDF, MLflow, Docker
A speech-to-text and document retrieval assistant packaged as a containerised service.
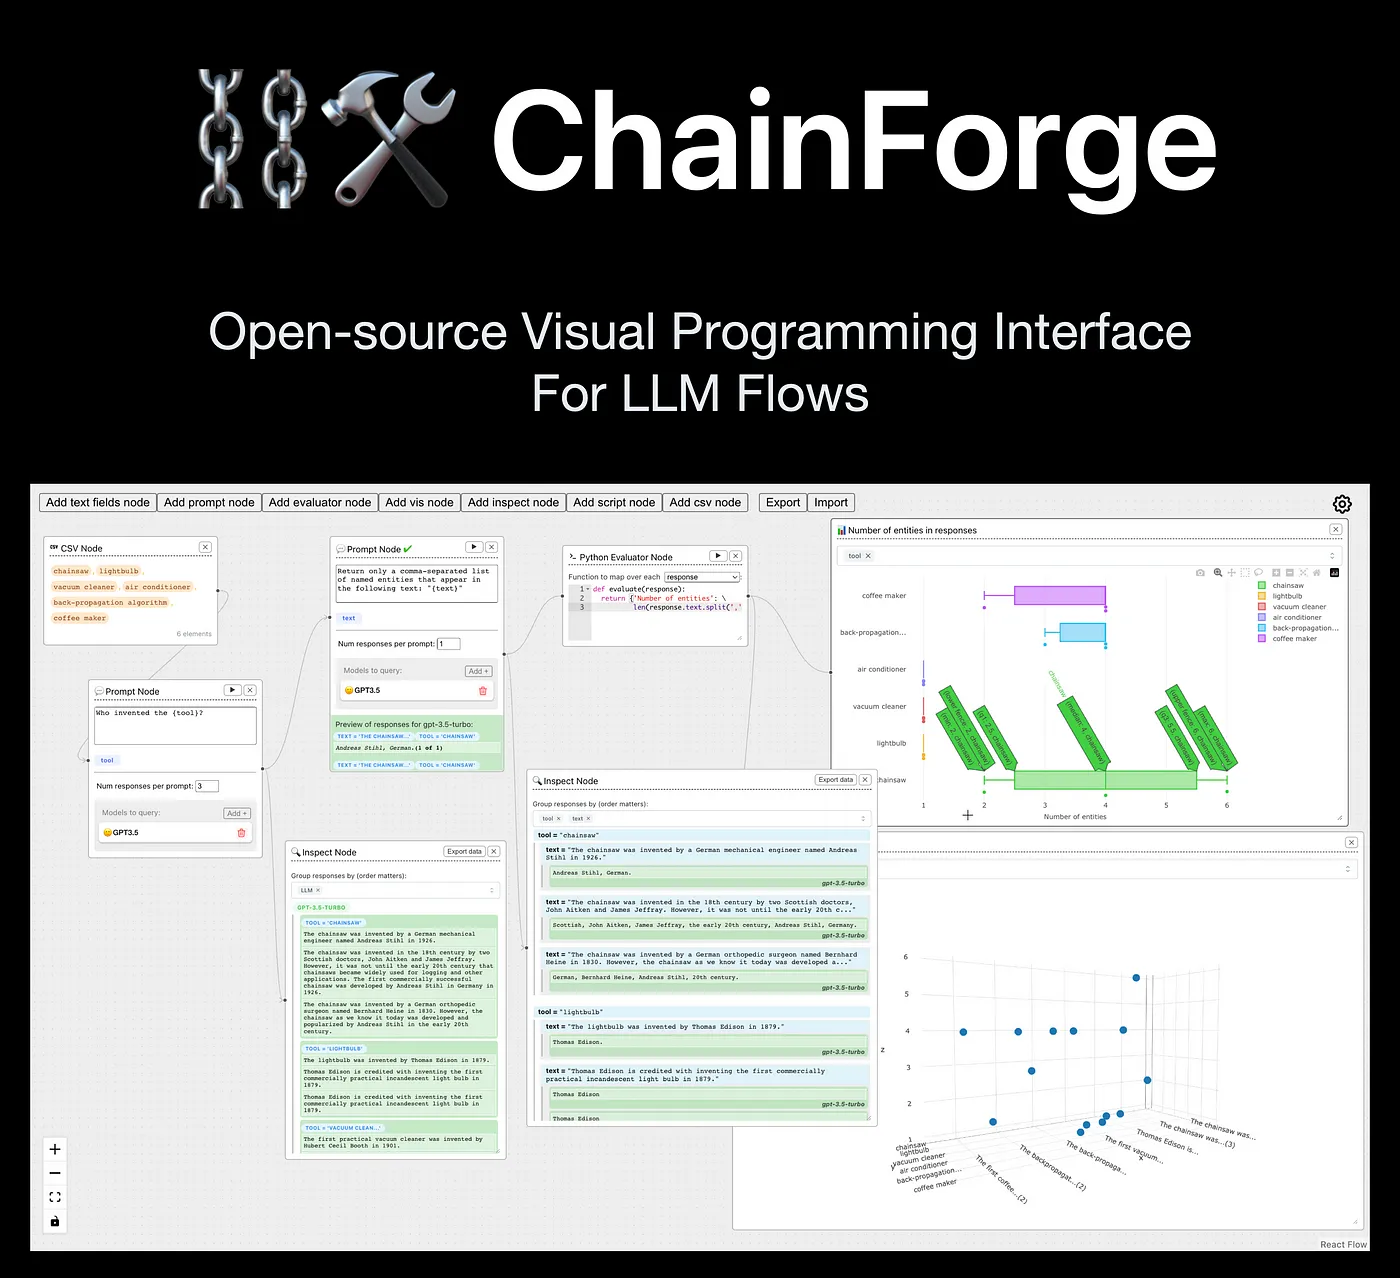 ChainForge, Llama 3, Mistral, Ollama
Systematic prompt engineering and model comparison at scale.
 pandas, numpy, matplotlib, seaborn, sklearn, xgb
A toolkit for measuring and mitigating bias in ML models, so their risks and limitations can be identified and counteracted.
4+ years delivering end-to-end LLM and data solutions in regulated, document-heavy enterprise environments. I build agentic workflows, RAG pipelines and document AI, and ship them to production with safety guardrails, systematic evaluation, and ongoing monitoring of quality, latency and cost.
• Built agentic AI workflows (coding and document-processing agents) with tool calling, structured outputs and automated verification of generated code, orchestrated via Prefect. They automate complex multi-step processing and significantly speed up turnaround for clients.
• Shipped end-to-end LLM solutions with advanced RAG pipelines (hybrid BM25 + dense retrieval, cross-encoder reranking) and optimised prompt design, turning static document repositories into context-aware search and Q&A.
• Developed document AI / OCR pipelines for unstructured data: ingestion, OCR and layout analysis (Mistral OCR, Docling, PaddleOCR), embeddings and structured extraction from scanned enterprise documents. Automated, validated extraction replaced manual review and cut processing time from days to hours.
• Built reproducible evaluation harnesses (Langfuse, DeepEval) covering retrieval recall, faithfulness and groundedness, and ran A/B benchmarks across prompt and model variants. This improved field-extraction accuracy by +20% F1 and made rollout decisions evidence-based.
• Monitored deployed LLM services for quality, latency and cost by benchmarking open-weight and proprietary models and analysing failure cases. This led to a switch to self-hosted open-weight serving, which significantly reduced inference cost at stable quality.
• Implemented LLM safety and compliance guardrails: prompt-injection mitigation, input/output validation, structured-output enforcement and GDPR-aware data handling. These enabled zero-incident enterprise deployment.
• Deployed all solutions to production as containerised microservices on self-hosted and cloud GPU infrastructure (Docker, FastAPI, Celery/Redis, vLLM, MLflow, CI/CD), with full control over data residency and cost.
• Lead weekly sessions prototyping and benchmarking new AI models and OCR/embedding approaches, build internal tooling for LLM development and evaluation, and mentor colleagues.
• Translated an automotive enterprise client's business requirements into technical ML designs and advised stakeholders on feasibility, data needs and model trade-offs. The resulting transformer models (multi-label classification, emotion detection, customer segmentation) directly shaped campaign targeting and marketing strategy.
• Built an automated Python pipeline combining topic modelling with zero/few-shot learning over 100k+ customer feedback items, integrated with internal APIs and databases. It cut manual analysis effort by ~40%.
• Applied SHAP and LIME and presented results to non-technical decision-makers, keeping model outputs transparent within cross-functional agile teams.
• Contributed to an AI-based persona project for the automotive sector using German and English datasets
• Fine-tuned transformer models (BERT, RoBERTa, T5) for text classification and emotion detection
• Benchmarked ML (sklearn) and DL (PyTorch) models for customer review insights
• Analysed customer interviews with spaCy to support persona development
Technical University of Munich
Thesis: Enhancing Text Simplification through Baby-Step Curriculum Learning: A Case Study on Privacy Policies Using the T5 Model
• Simplified complex privacy policy texts with a baby-step curriculum learning approach that structures training in progressive stages.
• Used the T5 Transformer and evaluated it with BLEU, SARI and FKGL metrics.
The stack I use most, grouped by where it fits in the system.
LangChain, LangGraph, Semantic Kernel, OpenAI API, Anthropic API, Gemini API, n8n
Ollama, vLLM, Groq, ONNX; Llama, Qwen, Mistral, DeepSeek
Mistral OCR, Chandra OCR, GLM-OCR, Docling, LayoutLMv3, PaddleOCR, Tesseract, PyMuPDF, PDFMiner, Textract, HURIDOCS layout analysis
Qdrant, FAISS, ChromaDB, Weaviate, Elasticsearch, Haystack, Neo4j; hybrid retrieval, cross-encoder reranking, GraphRAG
Ragas, DeepEval, ChainForge, Langfuse, NeMo Guardrails, LlamaGuard, SHAP, LIME
Transformers, TRL, PEFT / QLoRA, DeepSpeed, SentenceTransformers, Mixedbread, JinaAI
Docker, FastAPI, GitHub Actions, MLflow, DVC, Prefect, Airflow, Celery, Redis
AWS (EC2, Lambda, S3), Python, SQL, Pydantic, PostgreSQL, MongoDB, dbt, DuckDB
PyTorch, PyTorch Lightning, Scikit-learn, spaCy, NLTK, Pandas, NumPy
Streamlit, Gradio, Chainlit, Tableau, Plotly
I write practitioner-focused deep-dives on LLM internals, agent design and evaluation.
A two-part account of running self-hosted LLMs in production: infrastructure, costs and lessons learned.
A comprehensive guide to local LLM serving.
A deep dive into the 0.9B model that outperforms GPT-4o on document parsing.
How RAG systems fail in production, and how to catch it.
Build a knowledge graph from your entire codebase without sending your code to anyone.
A 13-part series on attention, training and the internal mechanics of large language models.
Alongside my professional work, I enjoy giving back to the community and helping others on their career paths.
Volunteer teacher in Machine Learning at ReDI School, helping to bridge the gap in technology education.
For a free one-on-one career guidance session, email me at mustafa.gencc94@gmail.com.